Category Archives: google

Marc Benioff: Google deal is aimed at a common enemy

Here at Dreamforce Europe, I asked Salesforce.com CEO Marc Benioff about the company’s agreement with Google, in which Salesforce becomes an OEM for Google Apps. We saw this demonstrated in the keynote. You can start a email via  Gmail from within a Salesforce contact. When sent – provided you click the Salesforce send button and not the Gmail send button – the email is added to the contact history. A similar feature lets you attach a Google document to a Salesforce record.

It’s a useful feature; but long term, will Salesforce.com and Google be competitors rather than partners? It is a natural question, since both companies are promoting their services as a platform for applications. Salesforce has the Apex programming language, while Google has its App Engine. According to Benioff, App Engine is primarily for Python developers, while Salesforce.com is a platform for enterprise applications. This struck me as downplaying Google’s likely ambitions in the enterprise market.

I therefore asked Benioff whether the agreement with Google included any non-compete element, or whether Google might be a future platform competitor. He did not answer my question, but said:

The enemy of my enemy is my friend

The identity of the enemy is unspecified; but given that Benioff used Microsoft .NET as the example of what his platform is supposedly replacing, and that Google docs competes with Microsoft Office, and that Benioff makes constant jibes at the complexity and expense of developing for Windows, I guess we can draw our own conclusions.

For sure, it did little to allay my suspicion that Salesforce.com and Google will not not always be as warm towards one another.

As an aside, there are ironies in Benioff’s characterization of .NET. Microsoft launched .NET as a “platform for web services”, which is exactly what Salesforce.com has become. Microsoft was a key driver behind the standardization and adoption of SOAP, which is the main protocol in the Salesforce.com API.

Live Mesh: Hailstorm take 2?

So says Spolsky, in a rant about both unwanted mega-architectures, and the way big companies snaffle up all the best coders.

Is he right? Well, I attended the Hailstorm PDC in 2001 and I still have the book that we were given: .NET My Services specification. There are definitely parallels, not least in the marketing pitch (from page 3):

.NET My Services will enable the end user to gain access to key information and receive alerts about important events anywhere, on any device, at any time. This technology will put users in total control of their data and make them more productive.

Swap “.NET My Services” for “Live Mesh” and you wouldn’t know the difference.

But is it really the same? Spolsky deliberately intermingles several points in his piece. He says it is the same stuff reheated. One implication is that because Hailstorm failed, Live Mesh will fail. Another point is that Live Mesh is based on synchronization, which he says is not a killer feature. A third point is that the thing is too large and overbearing; it is not based on what anyone wants.

Before going further, I think we should ask ourselves why Hailstorm failed. Let’s look at what some of the people involved think. We should look at this post by Mark Lucovsky, chief software architect for Hailstorm and now at Google, who says:

I believe that there are systems out there today that are based in large part on a similar set of core concepts. My feeling is that the various RSS/Atom based systems share these core concepts and are therefore very similar, and more importantly, that a vibrant, open and accessible, developer friendly eco-system is forming around these systems.

Joshua Allen, an engineer still at Microsoft, disagrees:

All of these technologies predate Hailstorm by a long shot.  There is a reason they succeeded where Hailstorm failed.  It’s because Hailstorm failed to adopt their essence; not because they adopted Hailstorm’s essence …. the “principles” Mark’s blog post cites are actually principles of the technologies Hailstorm aimed to replace.

but as Allen shows in the latter part of his post, the technology was incidental to the main reasons Hailstorm failed:

  1. Hailstorm intended to be a complete, comprehensive set of APIs and services ala Win32.  Everything — state management, identity, payments, provisioning, transactions — was to be handled by Hailstorm.
  2. Hailstorm was to be based on proprietary, patented schemas developed by a single entity (Microsoft).
  3. All your data belonged to Microsoft.  ISVs could build on top of the platform (after jumping through all sorts of licensing hoops), but we controlled all the access.  If we want to charge for alerts, we charge for alerts.  If we want to charge a fee for payment clearing, we charge a fee.  Once an ISV wrote on top of Hailstorm, they were locked in to our platform.  Unless we licensed a third party to implement the platform as well, kind of like if we licensed Apple to implement Win32.

Hailstorm’s technology was SOAP plus Passport authentication. There were some technical issues. I recall that Passport in those days was suspect. Some smart people worked out that it was not as secure as it should be, and there was a general feeling that it was OK for logging into Hotmail but not something you would want to use for online banking. As for SOAP, it gets a bad rap these days but it can work. That said, these problems were merely incidental compared to the political aspect. Hailstorm failed for lack of industry partners and public trust.

Right, so is Live Mesh any different? It could be. Let me quickly lay out a few differences.

  1. Live Mesh is built on XML feeds, not SOAP messaging. I think that is a better place to start.
  2. Synchronization is a big feature of Mesh, that wasn’t in Hailstorm. I don’t agree with Spolsky; I think this is a killer feature, if it works right.
  3. Live Mesh is an application platform, whereas Hailstorm was not. Mesh plus Silverlight strikes me as appealing.

Still, even if the technology is better, what about the trust aspect? Will Mesh fail for the same reasons?

It is too soon to say. We do not yet know the whole story. In principle, it could be different. Mesh is currently Passport (now Live ID) only. Will it be easy to use alternative authentication providers? If the company listens to its own Kim Cameron, you would think so.

Currently Mesh cloud data resides only on Microsoft’s servers, though it can also apparently do peer-to-peer synch. Will we be able to run Mesh entirely from our own servers? That is not yet known. What about one user having multiple meshs, say one for work, one personal, and one for some other role? Again, I’m not sure if this is possible. If there is only One True Mesh and it lives on Live.com, then some Hailstorm spectres will rise again.

Finally, the world has changed in the last 7 years. Google is feared today in the way that Microsoft was feared in 2001: the entity that wants to have all our information. But Google has softened us up to be more accepting of something like Live Mesh or even Hailstorm. Google already has our search history, perhaps our email, perhaps our online documents, perhaps an index of our local documents. Google already runs on many desktops; Google Checkout has our credit card details. What boundary can Live Mesh cross, that Google has not already crossed?

Hailstorm revisited is an easy jibe, but I’m keeping an open mind.

Microsoft: Live Mesh or Live Mess? Here’s what to read.

Here’s what I suggest you read to get to grips with Live Mesh:

Amit Mital’s introduction (he’s the General Manager)

Mike Zintel’s Live Mesh as a Platform (he’s Director of Service Infrastructure)

Mary Jo Foley’s Ten things to know and the helpful stack diagram.

I have a few initial comments. First, it’s the platform that matters, not the Live Desktop which is the first thing Microsoft is delivering and which you will find presented at mesh.com. Microsoft is finally showing us what it means by the “software plus services” thing it has been talking about for so long. It involves a new “Mesh Operating Runtime” which has both cloud pieces and client pieces, a MeshFX API, and an identity system which is Live ID (formerly Passport).

As far as I can tell, Microsoft is delivering an API which we will be able to use to build internet-based data, document and configuration into either desktop or web applications, with synchronization to local storage for offline use. Zintel adds:

… customers will ultimately license applications to their mesh, as opposed to an instantiation of Windows, Mac or a mobile account or a web site.  Such applications will be seamlessly installed and run from their mesh and application settings persisted across their mesh

It sounds good, though the obvious question is whether Microsoft is overstating the importance of the client in an attempt to preserve its core market. Do we need this special client piece? Here’s a paragraph from Zintel’s piece that caught my eye:

A key design goal of the Live Mesh data synchronization platform is to allow customers to retain the ownership of their data that is implicit with local storage while improving on the anywhere access appeal of the web. The evolution of the web as a combined experience and storage platform is increasingly forcing customers to choose between the advantages of local storage (privacy, price, performance and applications) and the browser’s implicit promise of data durability, anywhere access and in many cases, easy sharing.

Can Microsoft improve on the “anywhere access appeal of the web? Zintel says we need to combine it with the advantages of local storage, but the advantages Zintel identifies are not all that convincing. Let’s look at them:

Privacy: maybe, but local data is vulnerable to worms, trojans, viruses; well secured Internet data accessed over SSL is arguably more secure. Data not connected to the Internet is nice and secure, but can’t participate in the Mesh.

Price: I don’t see how Mesh helps here. Yes, local storage is cheap, but as soon as data enters the Mesh it is on the Internet and we are paying for data transfer as well as possibly Internet storage. I realise that Microsoft (among others) offers generous Internet storage for free, but that is just a way of buying market share.

Performance: Granted, some types of application work faster with local storage. Still, there are non-Mesh ways of getting this from web applications in a fairly seamless manner, such as Google Gears or Adobe’s AIR.

Applications: This is perhaps the big one. Many of us are reluctant to do without traditional local applications such as Office. Well, mainly Office. Still, web equivalents get better all the time. One day they will be good enough; and new technology like Silverlight is bringing that day closer. 

What about identity management and permissions? Zintel says:

A side effect of the competition to store customer data in the cloud and display it in a web browser is the fragmentation of that data and subsequent loss of ownership. Individual sites like Spaces, Flickr and Facebook make sharing easy, provided the people you are sharing with also use the same site. It is in fact very difficult to share across sites and equally difficult to work on the same data across the PC, mobile and web tiers.

True; but Mesh currently identifies users by their Live ID. Isn’t that the same as Spaces?

If Microsoft delivers a bunch of useful web services, that’s great. If it tries to somehow replace the web with its Mesh, it will fail.

Mary Jo Foley also asks the question: to what extent is Microsoft extending, and to what extent is it replacing, existing Live services such as Office Live or the excellent Skydrive? Making sense of all this is a challenge.

Now let’s mash all this up with Yahoo! (maybe). Ouch.
Britannica going more towards free

Towards free, not completely free. This is a fascinating example of old-school vs new school (Wikipedia and Google – I mean Google search, not the Knol thing). Britannica is opening up its content to “online publishers”, including qualifying bloggers – low traffic is OK, but infrequent posting is not. The idea is to encourage these users to post Britannica links on their sites. Such links will bypass the paywall, enabling non-subscribers to read articles that would otherwise require subscription.

We can debate the quality of Britannica’s more scholarly articles versus Wikipedia’s living encapsulation of crowd wisdom. The real question is this: what is Britannica’s business model when something that many people will feel is “good enough” is available for nothing?

Here’s what the FAQ says:

Won’t you lose money giving away all those subscriptions?

We don’t think so. On the contrary, with many Web publishers using our products and sharing them with our readers, we expect to see a lot more people subscribing.

On the other hand, might not existing subscribers feel that the value of their subscriptions is diminished by the giveaway?

I suspect this is an attempt to rebuild its brand and experiment with different business models, such as advertising.

Prediction: in time, Wikipedia will include more attributed and locked content, while Britannica will add user comments, ratings, and even entirely user-generated articles (marked as such, of course). In other words, they will converge. The winner will be the site with the most traffic. If I’m right, Britannica’s new initiative is right, but very late in the day.

As an aside, I thought this part of the FAQ was not very Britannica-like:

I blog regularly, but I don’t have much traffic. Will that disqualify me?

Nope. You need Britannica more than anybody. Start reading it, and your posts will burn with brilliant, scintillating insights; link to Britannica articles, and readers will be eternally grateful. Your traffic will soar.

Technorati tags: , ,

Amazon’s cloud computing to surpass its retailing business?

That’s what Larry Dignan is predicting.

I’m sceptical. I like what Amazon is doing with its infrastructure services, but I’m guessing they are low margin and price-sensitive; it’s going to be difficult to pump up its value to equal the retailing side.

My hunch is that Amazon will work at bringing its retailing and cloud computing businesses together. Look at the Flexible Payments Service and DevPay:

Amazon customers can pay using the same login credentials and payment information they already have on file with us. This helps Amazon customers keep their payment information secure and removes the friction you would face if you required customers to enter their payment information before they could make a purchase.

Sounds like a bank, right? Now look at what eBay is doing with PayPal (which it is moving towards making obligatory), and Google with Google Payments – note that the new AppEngine can use Google accounts as an identity service.

Banking is highly profitable. These three giants will be fighting over how to get a small slice of more of our Internet transactions – which will be an increasing share of our total transactions.

Like eBay, Amazon already has a strong business handling the storefront and payments for third parties in its marketplace.

I’ll be surprised if things like S3 and EC2 become more important to Amazon than its retailing; but I won’t be surprised if identity and financial services become the core of its business, rather than running warehouses and shipping out goods.

Update: clearly not yet.

Amazon Elastic Compute Cloud gets persistent storage

An annoying feature of Amazon EC2, a service which provides virtual servers on demand, is that server instances have no persistent storage. Any data written to the virtual hard drive disappears when the instance shuts down. Developers have needed to store data elsewhere, such as in Amazon’s S3 storage service.

Amazon has now announced persistent storage. These are virtual hard drives that you can attach to EC2 instances. Another enhancement since the initial launch is static IP numbers. Early tester (and reseller) Thorsten von Eicken is enthusiastic:

The feature that really makes the storage volumes sizzle is the ability to snapshot them to S3 and then create new volumes from the snapshots. The snapshots are great for durability: once a snapshot is taken it is stored in S3 with all the reliability attributes of S3, namely redundant storage in multiple availability zones. This essentially solves the whole backup issue with one simple API call.

It’s an excellent feature which arguably should have been there from the start.

Incidentally, I don’t know why people keep comparing Amazon’s web services with Google’s App Engine. OK, they are both cloud services. But Amazon is providing infrastructure services; Google is offering an application runtime. They hardly compete at all. Google and Amazon compete in other ways: Amazon marketplace vs Google Base and Google Checkout, for example.

Technorati tags: , , ,

Google App Engine: how much will you pay for freedom?

Google is offering to host your web apps for free:

You can create an account and publish an application that people can use right away at no charge, and with no obligation. An application on a free account can use up to 500MB of storage and up to 5 million page views a month.

What’s an application? It’s a runtime for Python apps (only Python code will run) and includes the Django web framework. There is a structured datastore which on the briefest of looks has echoes of Amazon’s SimpleDB and Microsoft’s SQL Server Data Services. Welcome to GQL – the Google Query Language. You can send email through Google’s servers (hmm, hope some work is being done to foil the spammers). You can use Google Accounts as an identity service – this is a big one, since it helps Google to meld your online identity with its services.

So what’s the business model? Google says:

During this preview period, only free accounts are available. In the near future, you will be able to purchase additional computing resources at competitive market prices. Free accounts will continue to be available after the preview period.

There are a few clues about what will constitute an “additional computing resource”. Clearly storage is one limit, and there is also a limit of 3 applications for free accounts. There is also a reference to bandwidth limits, the number of results you can return from a query (1000), and the length of time taken to serve a web request.

Apps communicate through HTTP or HTTPS requests. No talk of SOAP or even XML that I can see, though presumably you can use Python libraries.

Although we talk a lot about the largest applications that need to scale, this is a minority of real-world applications. Many of today’s web applications could run happily for free on Google’s new service, once ported. The economics interest me. Google is offering to subsidise our web infrastructure even further than it does already with GMail, Blogger and iGoogle gadgets. Therefore, if we choose to host our own services we have to pay for the flexibility and control that gives us, as well having to deal with scalability and security issues that Google will otherwise look after for us. In the light of generous app hosting offers like this, how much are we willing to pay for that freedom?

A real-world account of Google Adsense – and it doesn’t look good

Advertising is “the economic engine that powers the Web”, according to Microsoft’s Ray Ozzie. Google’s rapid ascendancy, enabled by advertising revenue, is the primary evidence for this. That said, Rick Strahl’s post on Google advertising highlights several problems with Google’s approach. It is about Adsense, the mechanism by which third-party sites (like this one) host Google advertising. When someone clicks an ad, Google gets paid, and an undisclosed percentage of the fee goes to the site owner.

Strahl runs a small business and uses Google both as advertiser and web site owner. He’s puzzled by the stats he’s gathered at both ends. As advertiser, he says that 30-40% of his hits come from link parking sites, plus another 10% which have no referrer, and reckons that these hits are worthless and in many cases possibly fraudulent. That’s up to 50% of wasted ad spend. Google tells him there is no way to opt out of link parking sites, other than by excluding specific sites; but since there are thousands of such sites and they change constantly, that is impractical.

At the other end, Strahl sees frequent deductions from the clicks on his own site, presumably on the basis that they are fraudulent or accidental (such as robot clicks). In fact, deductions from his site, which he controls and which has good, genuine content, appear to be far higher than those from the link parking sites which have no real content at all. In other words, Google seems happier to make deductions from what it pays to him, than from what he pays to Google.

He’s also curious about the ad bidding process, which always seems to end up charging him the maximum possible.

It’s possible that he has some of this wrong; but there is no way to audit Google’s figures:

In the end it feels like black magic. Google (and other advertisers as well to be fair) control the process so completely that if there’s any foul play either on Google’s part or for cheating publishers that contest clicks on the other end there’s almost no real way to tell that it’s happening and unless you have the time to keep very close tabs on it there’s no way to follow the money all the way through – on both ends. And who has that kind of time?

I find this unsurprising. The pay-per-click model has always seemed to me far too vulnerable to abuse, especially bearing in mind all those botnets. Who pays for any fraud? Not Google, but Google’s customers, the advertisers.

Some level of click fraud is inevitable, but Google’s willingness to let any old worthless bot-driven link parking site run Adsense ads is a disgrace. This stuff poisons the web, because it provides a financial incentive to post junk.

Advertisers can opt-out of Adsense, by disabling the “content network” for the ads they place. If enough advertisers do this, Google will take note.

Disclosure and to add a personal note: I am an Adsense publisher, though not an advertiser. I also use Blogads, which to my mind has a better business model for advertisers, since they specify exactly which sites they wish to use. In addition, I get to approve each ad, whereas with Adsense I have to take whatever comes. The snag is, Blogads is tiny in comparison to Google, which can seemingly always supply ads for my site.

Technorati tags: , ,


Is Google Gears safe?

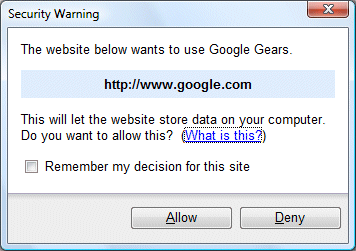
I imagine that is the question most users will ask when they see this dialog:

There are a couple of things I don’t like about this dialog. First, the website is defined only by an URL. The problem is, it’s a plain http connection so there’s no SSL certificate involved, so I can’t easily check the identity of the site. This one is Google, so it’s not too difficult; but what if it is some other site? It is not particularly easy to verify the ownership of an URL; whois information is not reliable.

Second, what are the implications of my decision? If you click What is this, you get this page, which explains offline functionality but doesn’t mention security. It does mention that Gears is a beta – personally I think this should be up-front in the security warning dialog as well. Do you trust this beta software?

If you go to the Frequently Asked Questions, there is still no mention of security. Is nobody asking about it? This article is the closest I can see, but merely repeats the information in the original dialog, that Gears allows websites to write to my computer. Enquiring minds ask: where can they write data? Where can they read data? Could they install malware or execute code?

We could do with a link to this page, about the Gears security model. This tells me that Gears uses a same origin policy:

A web page with a particular scheme, host, and port can only access resources with the same scheme, host, and port.

It also says:

Google Gears data files are protected with the user’s operating system login credentials. Users with separate login names cannot access each other’s Google Gears data files, as enforced by the operating system.

The bit about “as enforced by the operating system” should be highlighted. If your users have local admin rights, as on some Windows boxes, they will be able to access files belonging to other users.

But is Gears safe? What if I’m taken in by a scam site and give it permission to use Gears?

It may not be too bad. Gears can’t write anywhere on my hard drive, only to a location in my local profile or home directory. It doesn’t use the browser cache, presumably because it isn’t reliable; it may get cleared. Still, I guess some sort of attack might be possible along the lines of: write an executable to my local resource store, then give me a link to click and run it. Gears could fill your home directory with stuff you do not want, of course, but that’s the explicit permission you give when you agree to let a site write to your computer.

This presumes that Gears does not have security bugs. There may be and probably are ways to mount attacks using Gears that I have not thought of.

Bottom line: Gears is probably fairly safe, provided that the site really is trustworthy, but it is a beta and the usual caveats apply. Check that URL carefully. Avoid Gears when used by smaller organizations that might not have sites well defended against malware. I still don’t like the dialog though; and I’m surprised that Google does not make it easier for users to examine the security issues.

This post is prompted by yesterday’s announcement of Offline access to Google Docs.

QCon London

Today I’m at QCon in London. I enjoyed this conference last year, when among other things I got the scoop on Microsoft’s Volta (then LINQ 2). First up this year is Erich Gamma of Design Patterns and JUnit fame, who will be talking about how Eclipse has influenced his view of software development (others would talk about how Gamma has influenced Eclipse). I’m also intrigued by what Google’s Gregor Hohpe is going to say about “The Cloud as the new middleware platform.” It’s going to be an interesting contrast to Microsoft’s Mix08 conference last week. Be sure I’ll be reporting back here; or if you’re here too, by all means get in touch.

Technorati tags: , , ,