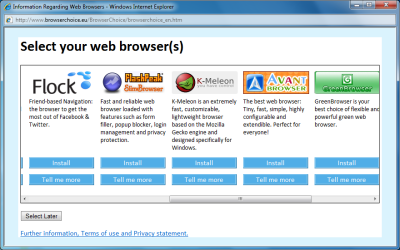
The bizarre story of the EU-mandated Windows browser choice screen took an unexpected twist recently when it was noticed that the order of the browsers was not truly random.
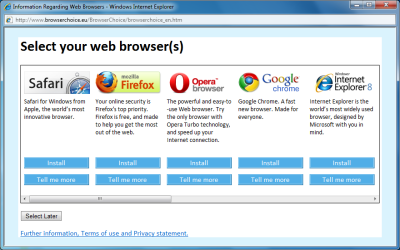
IBM’s Rob Weir was not the first to spot the problem, but did a great job in writing it up, both when initially observed and after it was fixed by Microsoft.
It was an algorithm error, a piece of code that did not return the results the programmer intended.
Unless Microsoft chooses to tell us, there is no way to tell how the error happened. However, as Weir and others observe, it may be significant that a Google search for something like Javascript random sort immediately gets you sample code that has the same error. Further, the error is not immediately obvious, making it particularly dangerous.
I am sure I am not the only person to turn to Google when confronted with some programming task that requires some research. In general, it is a great resource; and Google’s own algorithms help a little with filtering the results so that sites with better reputation or more inbound links come higher in the results.
Still, what this case illustrates – though accepting again that we do not know how the error occurred in this instance – is that pasting code from a Google search into your project without fully understanding and testing it does not always work. Subtle bugs like this one, which may go unnoticed for a long time, can have severe consequences. Randomisation is used in security code, for example.
As an aside, there also seems to be some randomness in the appearance of the browser choice screen. It turned up on my laptop, but not on my desktop, although both have IE as the default.
And who would have guessed that the EU would arrange for so many of us to get an ad for something like the GreenBrowser popping up on our desktop? Apparently it is the “best choice of flexible and powerful green web browser”, though since it is based on IE it is less radical a choice than it first seems.